Most conversations about artificial intelligence tend to focus on text generation, image synthesis, or the latest large language model benchmark. But there is an equally important and considerably less flashy category of AI tooling: evaluation models. Jev, built by TypeSafe AI, sits squarely in that space — and it does so with a very specific, well-defined technical proposition.
What Is Jev and What Problem Does It Solve?
Jev is described as TypeSafe AI's System One evaluation model. The "System One" label borrows from the cognitive framework popularized by Daniel Kahneman, referring to fast, intuitive thinking as opposed to the slower, deliberate reasoning of "System Two." Applied to software, this means Jev is engineered for high-speed structured decisions — without the latency or computational cost associated with deep reasoning models.
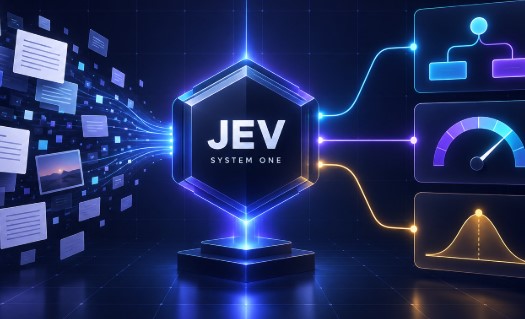
The core mechanism is straightforward: Jev receives a shared state — which can be a text snippet, a JSON structure, a document, or any relevant context — and evaluates it against a set of typed questions. The model then returns three kinds of outputs:
- Choices: structured selection from predefined alternatives.
- Scores: numeric values that quantify quality or relevance according to a rubric.
- Boolean probabilities: confidence estimates for whether a given condition is true or false.
Critically, multiple questions can be evaluated in parallel within a single request, reducing overall latency and simplifying the architecture of systems that integrate Jev into their pipelines.
Core Use Cases: Classification, Routing, and Automated Verification
TypeSafe AI has outlined four primary application areas for Jev, all of them common in enterprise software workflows:
- Classification: determining which category an item belongs to — a support ticket, a code snippet, a user review — without spinning up a full generative model.
- Routing: deciding which agent, function, or service a request should be directed to within a multi-agent system or microservices architecture.
- Rubric-based assessment: automatically scoring responses, documents, or code against predefined criteria — useful in QA pipelines, automated code review, or edtech platforms.
- Automated verification: checking whether an output meets specific requirements — test coverage thresholds, policy compliance, semantic consistency — without human intervention.
This combination of capabilities makes Jev a particularly valuable component in compound AI architectures, where multiple models or agents collaborate and require fast, reliable quality-control and decision mechanisms between steps.
Available Through Vercel AI Gateway
Jev is accessible via Vercel AI Gateway, the platform that consolidates access to a growing catalog of AI models under a single unified API. For development teams already embedded in the Vercel ecosystem, this means Jev can be added to existing projects without managing separate credentials or custom integrations with TypeSafe AI directly.
Being part of Vercel AI Gateway also brings observability tooling, cost controls, and quota management out of the box — a meaningful advantage when Jev is deployed in production environments handling high volumes of parallel evaluation requests. The playground environment available on the Gateway also allows teams to prototype and test evaluation patterns before committing to production implementation.
Why Strict Typing Actually Matters Here
The name "TypeSafe AI" is not cosmetic. One of the most persistent pain points when integrating language models into production applications is the non-deterministic, loosely structured nature of their outputs. Jev addresses this at a fundamental level: questions are typed, and responses conform to predictable schemas. This dramatically simplifies integration with strictly typed systems — those built with TypeScript, Go, Rust, or similar languages — and reduces the need for additional validation layers and error-handling boilerplate.
For engineering teams that prioritize reliability and traceability in their data pipelines, this is not a minor convenience: it is a fundamental requirement that traditional generative models rarely satisfy natively. Wrapping a generative LLM to produce structured outputs is possible, but it introduces fragility. Jev is built structured from the ground up.
As AI becomes more deeply embedded in critical software decisions — routing customer requests, verifying code quality, scoring content at scale — tools like Jev represent a meaningful maturation of the field. Not every AI integration needs to be a chatbot or a creative co-pilot. Sometimes what a system needs is a fast, precise, predictable evaluator running quietly in the background, keeping quality high and decisions consistent. That is exactly the niche Jev is designed to fill.